Note: This article is available in Chinese only. 本文暂无英文版本。
View original
背景#
2022年惊讶的发现,当时竟然没有写关于softmax的笔记,因此来补充一下。
proto#
还是先看proto
 1
 2// Message that stores parameters used by SoftmaxLayer, SoftmaxWithLossLayer
 3message SoftmaxParameter {
 4  enum Engine {
 5    DEFAULT = 0;
 6    CAFFE = 1;
 7    CUDNN = 2;
 8  }
 9  optional Engine engine = 1 [default = DEFAULT];
10
11  // The axis along which to perform the softmax -- may be negative to index
12  // from the end (e.g., -1 for the last axis).
13  // Any other axes will be evaluated as independent softmaxes.
14  optional int32 axis = 2 [default = 1];
15}
axis表示在哪个维度进行softmax
c++ 实现#
由于计算过程中可能存在溢出的情况,所以这里的技巧是,把所有的元素变换到小于0的区间
这样做可以保证数值上不会溢出,且计算结果不会发生改变
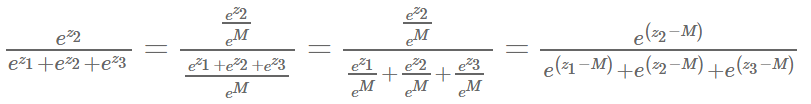
 1
 2template <typename Dtype>
 3void SoftmaxLayer<Dtype>::Forward_cpu(const vector<Blob<Dtype>*>& bottom,
 4    const vector<Blob<Dtype>*>& top) {
 5  const Dtype* bottom_data = bottom[0]->cpu_data();
 6  Dtype* top_data = top[0]->mutable_cpu_data();
 7  Dtype* scale_data = scale_.mutable_cpu_data();
 8  int channels = bottom[0]->shape(softmax_axis_);
 9  int dim = bottom[0]->count() / outer_num_;
10  caffe_copy(bottom[0]->count(), bottom_data, top_data);
11  // We need to subtract the max to avoid numerical issues, compute the exp,
12  // and then normalize.
13  for (int i = 0; i < outer_num_; ++i) {
14    // initialize scale_data to the first plane
15    caffe_copy(inner_num_, bottom_data + i * dim, scale_data);
16    for (int j = 0; j < channels; j++) {
17      for (int k = 0; k < inner_num_; k++) {
18        scale_data[k] = std::max(scale_data[k],
19            bottom_data[i * dim + j * inner_num_ + k]);
20      }
21    }
22    // subtraction
23    caffe_cpu_gemm<Dtype>(CblasNoTrans, CblasNoTrans, channels, inner_num_,
24        1, -1., sum_multiplier_.cpu_data(), scale_data, 1., top_data);
25    // exponentiation
26    caffe_exp<Dtype>(dim, top_data, top_data);
27    // sum after exp
28    caffe_cpu_gemv<Dtype>(CblasTrans, channels, inner_num_, 1.,
29        top_data, sum_multiplier_.cpu_data(), 0., scale_data);
30    // division
31    for (int j = 0; j < channels; j++) {
32      caffe_div(inner_num_, top_data, scale_data, top_data);
33      top_data += inner_num_;
34    }
35  }
36}